Robot Learning & Human-Robot Interaction

I build robots that
understand people.

I’m a first-year master’s student in Robotic Systems Development at the CMU Robotics Institute. For my MRSD capstone, I work with Nissan on a vision-language-action manipulation stack for the Unitree G1, retargeting human factory video for policy pre-training. I also work at the HARP Lab, led by Henny Admoni, on multimodal human-in-the-loop reward learning for out-of-distribution adaptation of visuomotor policies.

Before CMU I spent four years at Honda R&D Tokyo, where I built vision-language interaction and egocentric perception for autonomous micro-mobility robots, deployed in public proof-of-concept trials.

Mayanka Medhe
Affiliations
CMU
ex-Honda R&D Tokyo
UTokyo
IIT Bombay

Selected work

CMU × Nissan2026–present

Learning manipulation from human video

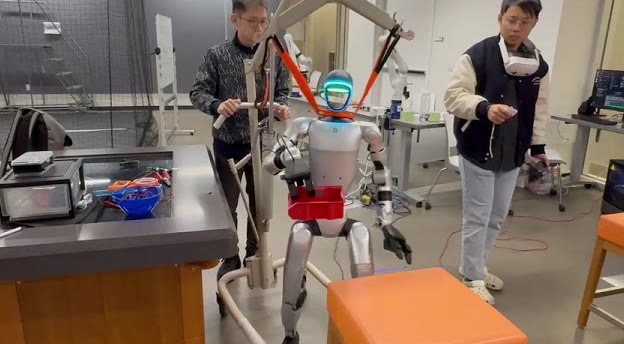
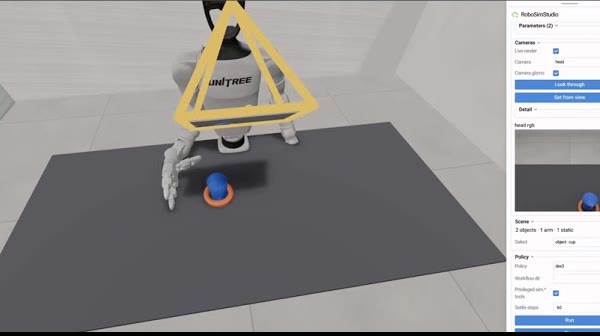
Teleoperated demonstrations do not scale on a factory floor. My capstone asks whether a Unitree G1 humanoid can learn manipulation mainly from ordinary human video, retargeted onto the robot through NVIDIA’s SONIC whole-body controller, and we’re evaluating vision-language-action models such as GR00T and π0.7 for policy learning.

In progressNissan-sponsored
CMU2026

FAR: faster agentic robotics

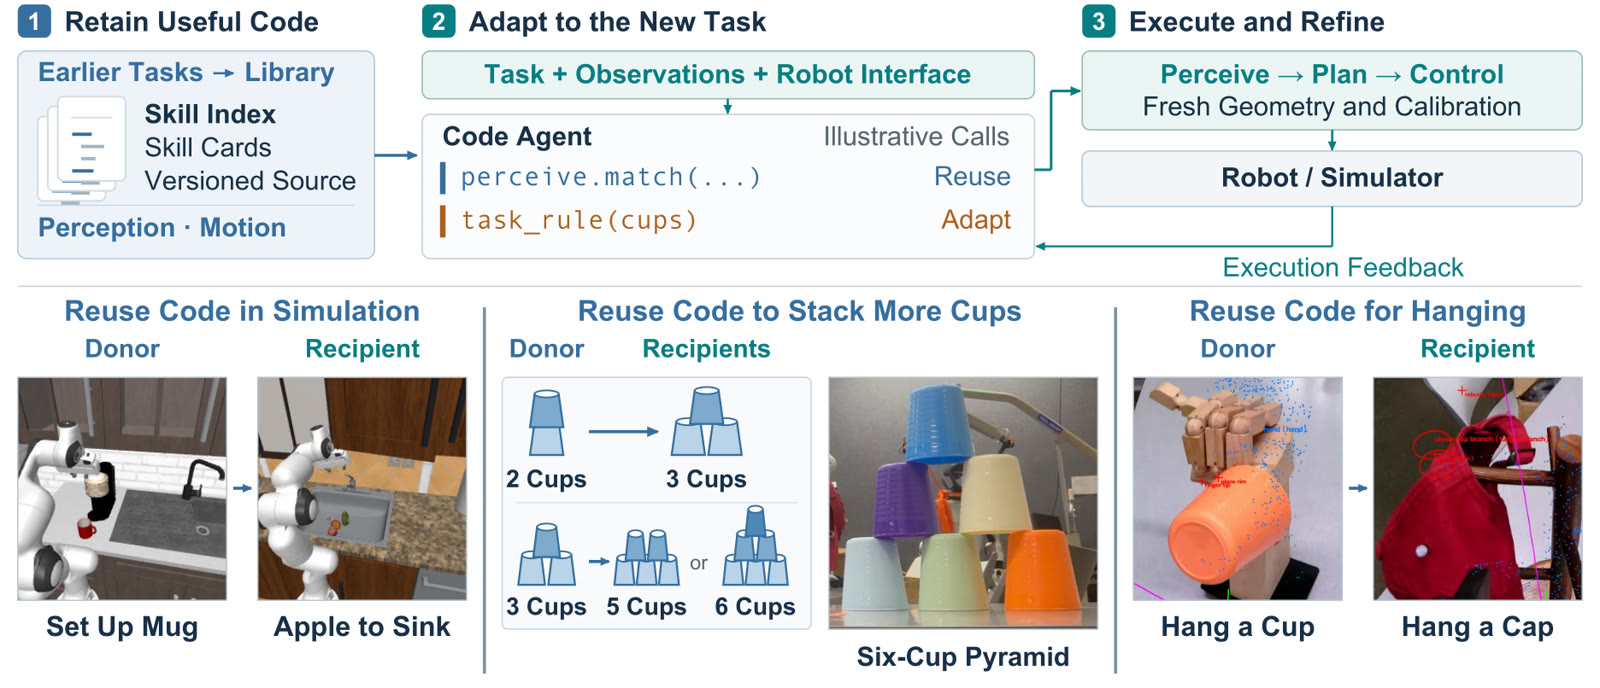
Coding agents rebuild perception and motion code from scratch for every new task, which costs time and tokens. FAR lets the agent reuse tested code from a similar task on the same arm, adapt it, and refine it from execution feedback. Evaluated on 5 simulated tasks and 10 real-robot transfers across two Kinova Gen3 arms. Co-first author, advised by Jeffrey Ichnowski.

42 skillsacross 7 donor libraries

CMU2026

Whole-body VR teleop of the G1

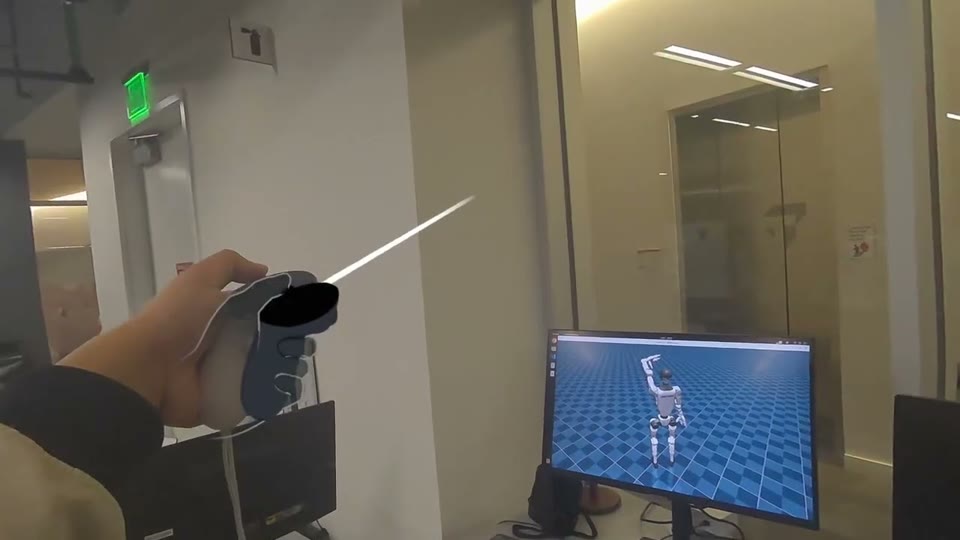
Whole-body teleoperation of a Unitree G1 with dexterous hands, driven by NVIDIA’s SONIC whole-body controller from a neck-mounted Meta Quest 3S. Body-follow walking, hot handover into learned control without a gantry, all running on an onboard Jetson Orin NX. Equal contribution.

29-DOFwhole-body control, fully onboard

CMU2026

F1TENTH autonomous racing

A 1:10-scale autonomous race car: 2D LiDAR particle-filter localization, RRT* planning tracked by pure pursuit, and follow-the-gap for reactive obstacle avoidance, raced head-to-head on a tight indoor track.

4thof 10 teams

Honda R&D Tokyo2025–2026

Text-guided map retrieval

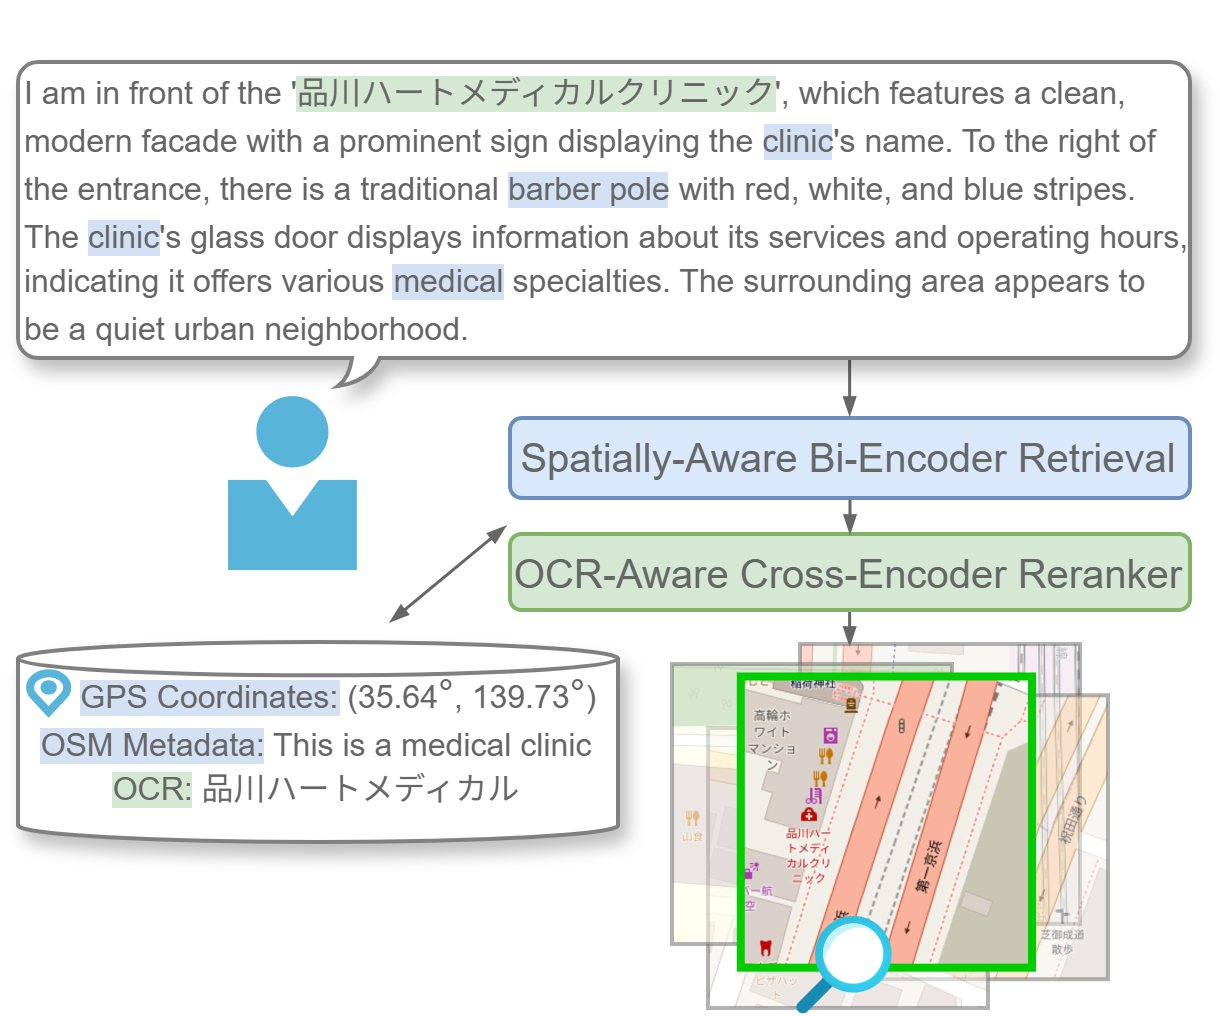
Localizing from vague language such as “the café near the second crossing.” A GPS-contrastive CLIP bi-encoder retrieves candidate map tiles, an OCR-aware cross-encoder re-ranks them, and a point is predicted within the top tile.

+18.6 ppR@1 over SOTA

Honda R&D Tokyo2022–2026

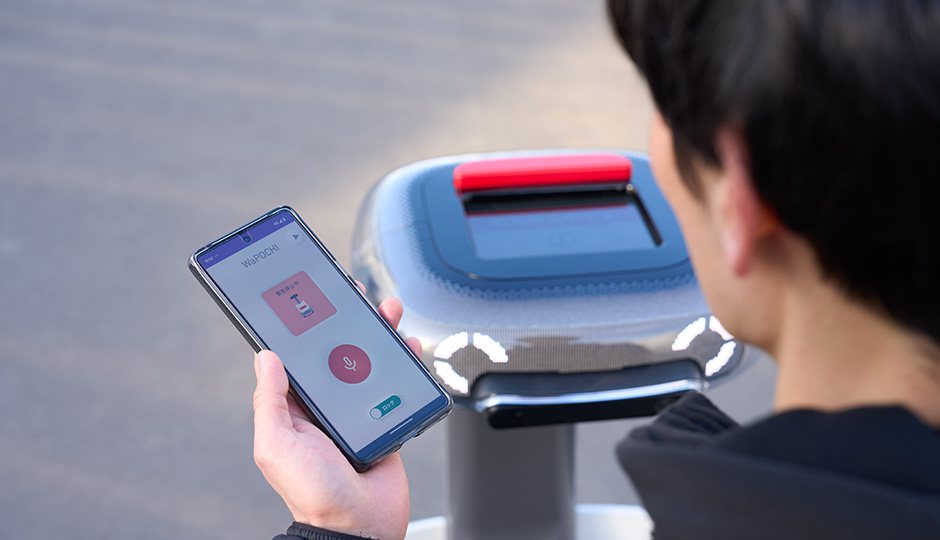
Smartwatch-robot interaction

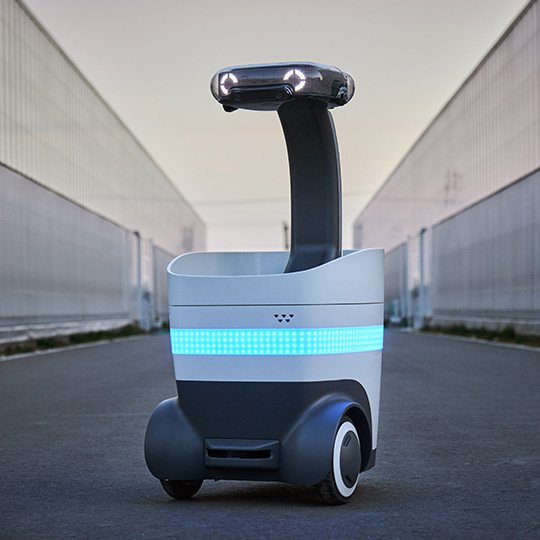
VLM-based voice-intent recognition on a smartwatch, grounded into robot control commands for autonomous micro-mobility. Deployed in a public proof-of-concept in unstructured outdoor environments and showcased at IFAC 2023.

5,000+users reached

Honda R&D Tokyo2024

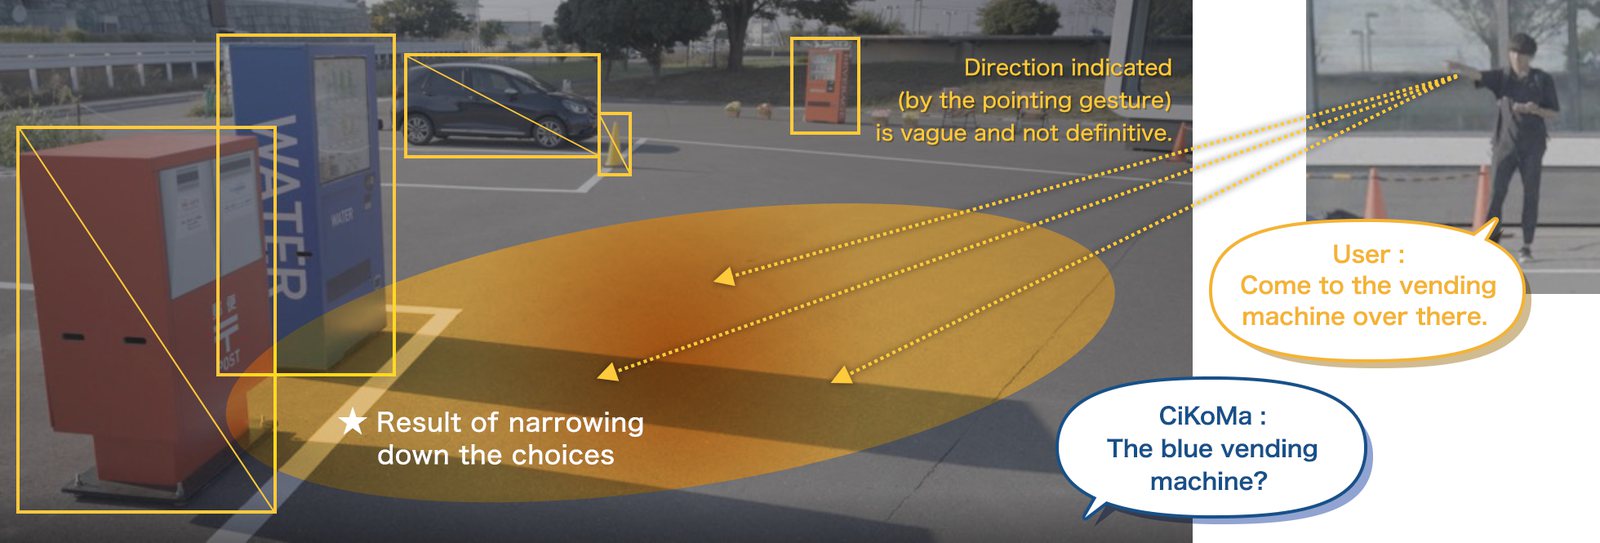
Pointing-gesture stop estimation

Point at the curb and the vehicle stops there. Eye and fingertip keypoints are triangulated from stereo 3D pose, and the eye-to-fingertip ray is intersected with the ground plane to get the stop position, with no map pin or spoken address.

Patentapplication filed

Honda R&D Tokyo2023–2024

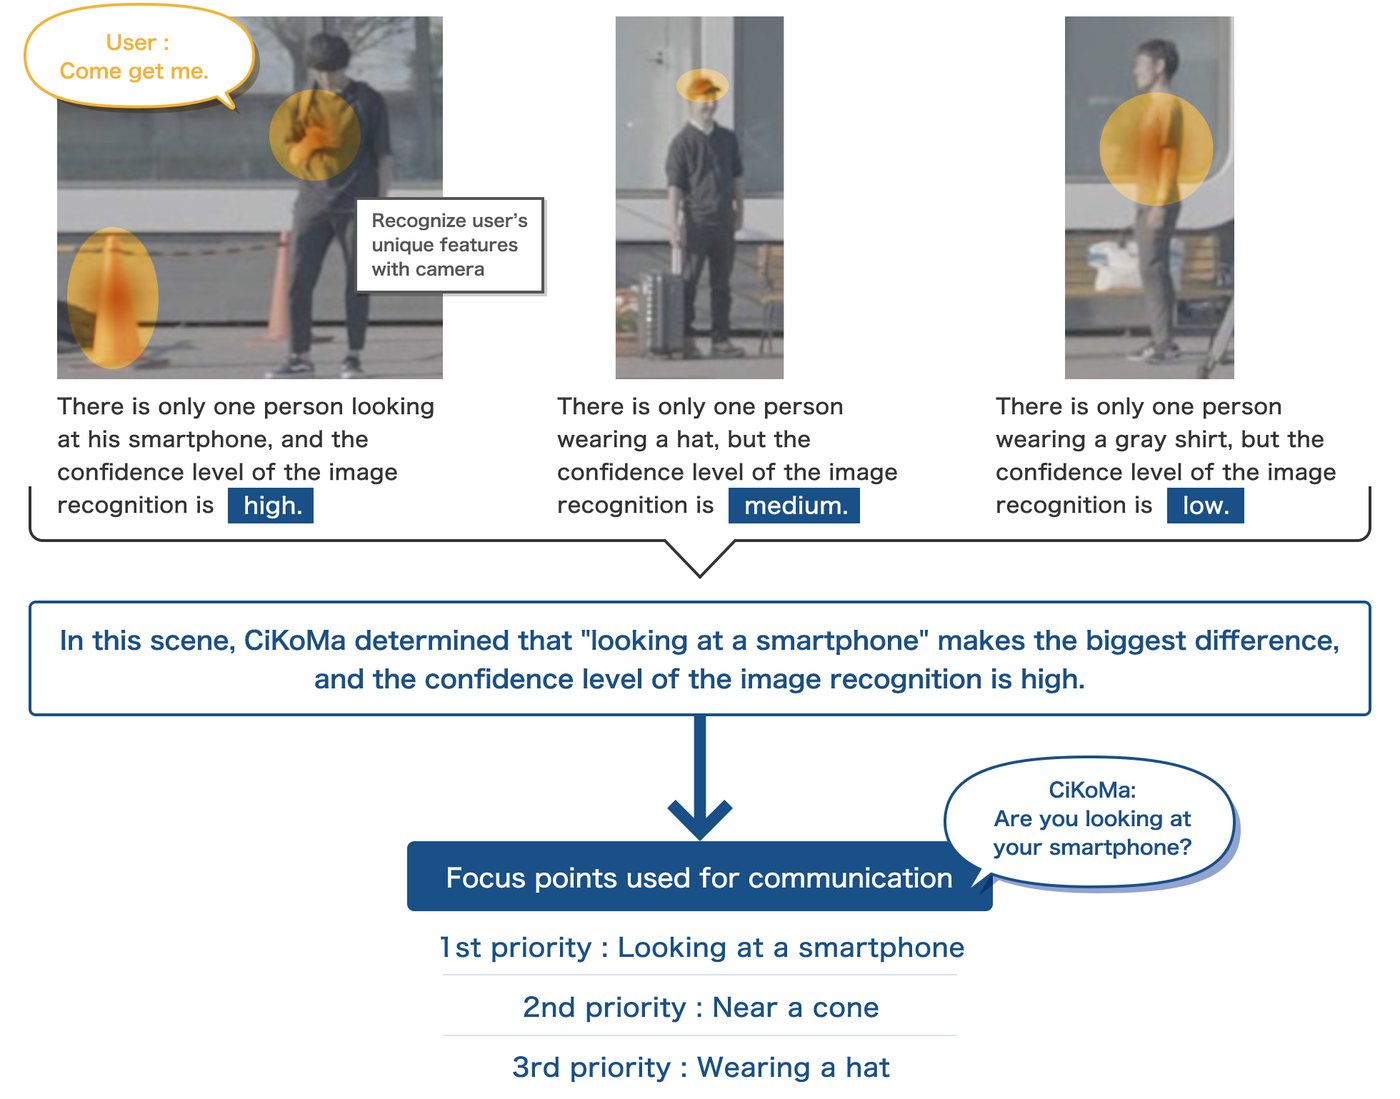
Who to follow in a crowd

User re-identification from fine-grained pedestrian attributes, choosing the most discriminative attribute among nearby pedestrians so the robot keeps its user while leading or following through a busy street. TensorRT-optimized for Jetson.

Real-timeon-device inference

Sato Lab, UTokyo2020–2022

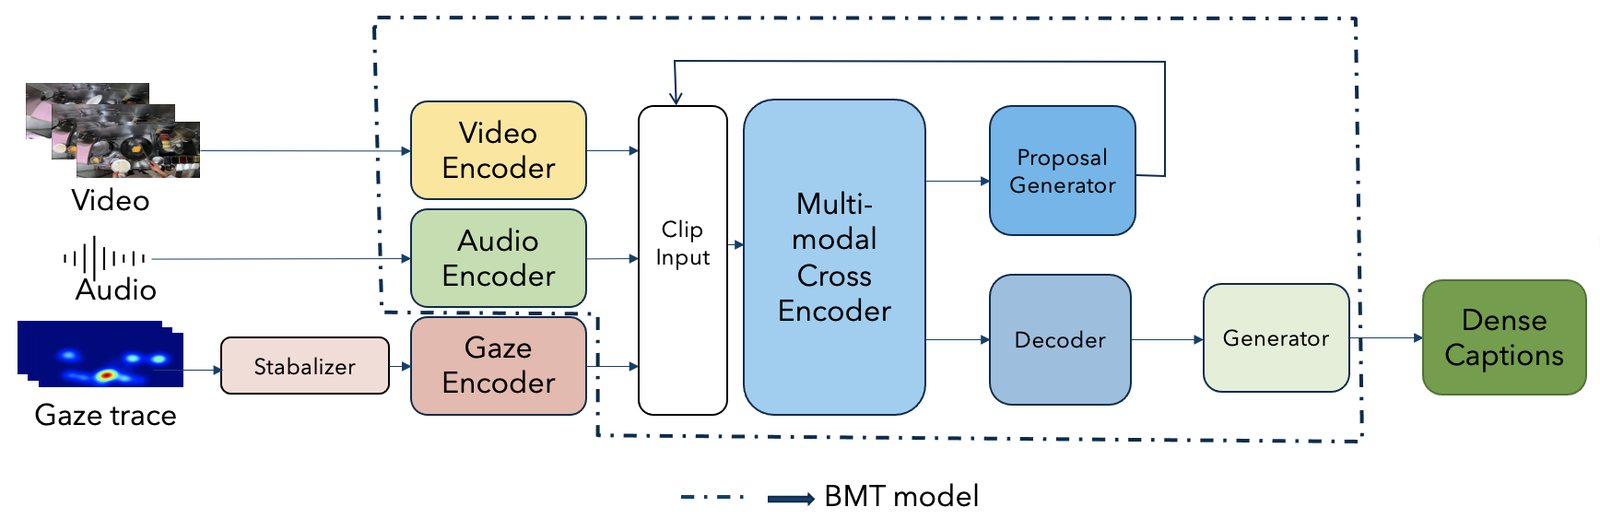
Gaze-guided video captioning

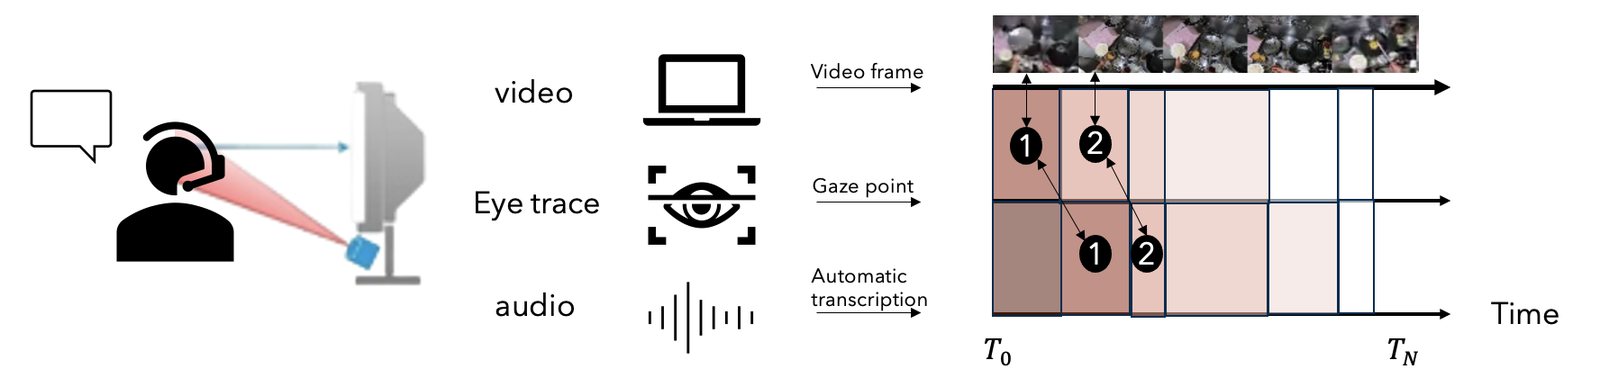
Where a person looks tells you what matters in a scene. I folded eye-gaze priors into I3D features through attention maps for dense video captioning, and released a gaze-aligned description dataset covering 2.5 hours, 33 viewers, and 15 languages.

+24.4%action grounding

Experience

  • Sep 2026–present

    Robot learning research

    HARP Lab, CMU

    Multimodal human-in-the-loop reward learning that adapts visuomotor policies to out-of-distribution settings in real time.

  • Sep 2022–Aug 2026

    Research Engineer, Human-Robot Interaction

    Honda R&D · Tokyo

    Multimodal perception and interaction for autonomous micro-mobility robots, CiKoMa and WaPOCHI. Led the vision-language interaction system through public deployment, built pointing-gesture and pedestrian-attribute perception, and proposed the text-guided map retrieval method now under patent.

    Honda R&D Executive Award
  • May 2021–Oct 2021

    Research Engineer, Sensing & Perception

    Tier IV · Tokyo

    ROS-based object detection evaluation framework for autonomous driving, flagging false positives and negatives across weather conditions.

  • Oct 2020–May 2022

    Research Assistant

    Sato Lab, University of Tokyo

    Multimodal video understanding with eye gaze and natural language, in collaboration with RIKEN CBS.

  • May 2018–Jul 2018

    Research Engineer, Vision Team

    Honda Research Institute · Wako

    Adaptive-resolution 3D volumetric mapping from ORB-SLAM2 point clouds for world modeling on the ASIMO bipedal robot.

Publications & patents

  • FAR: Faster agentic robotics with fewer tokens

    Mayank Chandak*, Shi Chen*, Yu-Lun Chou*, Vamsi Grandhi*, Mayanka Medhe*, Jeffrey Ichnowski (equal contribution)

    Preprint, arXiv forthcoming · 2026

  • Two-step spatially-aware and OCR-grounded map tile retrieval and point prediction for text-guided localization

    Mayanka Medhe, Naoki Hosomi

    Invention disclosure filed, Honda · 2026

  • User localization in camera space using combined user and surrounding object information

    Mayanka Medhe, Naoki Hosomi

    PCT patent application No. PCT/JP2025/030309 · 2025

  • Improving reasoning for outdoor navigation using commonsense knowledge insertion

    Mayanka Medhe, Anirudh Reddy Kondapally, Kentaro Yamada, Hitomi Yanaka

    SICE Annual Conference · 2023

  • Transformer-based reinforcement learning for games

    Uddeshya Upadhyay*, Nikunj Shah*, Sucheta Ravikanti*, Mayanka Medhe* (equal contribution)

    arXiv preprint · 2019

Education

Toolkit

ML & perception

  • PyTorch
  • VLMs / CLIP
  • Transformers
  • ORB-SLAM2
  • Pose estimation
  • Stereo vision
  • TensorRT

Robotics

  • ROS / ROS2
  • MuJoCo
  • Gazebo
  • MoveIt
  • VR teleoperation
  • Motion planning (RRT*)
  • Coding agents
  • Edge deployment

Engineering

  • Python
  • C++
  • CUDA
  • Docker
  • Linux
  • CI/CD
  • SQL

Languages

  • English
  • 日本語
  • हिन्दी
  • मराठी

Beyond the lab

  • 2024

    Farm volunteer, rural France Sustainable farming, animal care, and permaculture maintenance.

  • 2021–2022

    Instructor, Saturday Kids Japan Coding and robotics workshops for children aged 5 to 14, using Scratch, Minecraft, and LEGO Robotics.

  • 2021–2022

    Volunteer, ISA Japan Empowerment and English-speaking programs at high schools across Japan.